llms.txt Setup Guide: Structure Your Site for AI Engines
Key answerThe llms.txt setup guide helps web publishers present clean, markdown-formatted context directly to AI crawlers. By placing a standardized `/llms.txt` file in your website root, you provide language models with concise product summaries, clear entity definitions, and direct links to essential resources without HTML navigation bloat.
Modern search engines and conversational AI systems process information differently than traditional web crawlers. When an AI agent scans your website, HTML markup, navigation bars, and tracking scripts consume valuable context tokens. A practical llms.txt setup guide allows you to strip away visual clutter and offer search bots exactly what they need: structured, factual markdown text.
What is llms.txt and why does it matter for GEO?
The llms.txt proposal is an open standard designed to serve AI agents and large language models concise information about a project or business. Similar to how robots.txt governs crawler permissions, llms.txt directs generative engines to high-value markdown representations of your web pages.
When OpenAI Search, Perplexity, or Claude inspects a domain, processing megabytes of nested JavaScript and inline styling introduces parsing errors. By maintaining a clean file at the root path, you establish a reliable source of ground truth for your brand, offerings, and technical documentation.
The 3-Layer llms.txt Hierarchy Framework
To prevent context bloat while providing thorough technical depth, I use a tiered structure across website assets:
Layer 1: The Root Manifest (/llms.txt)
The root manifest contains your organization title, a two-sentence mission summary, and a curated list of your most important URLs accompanied by one-line descriptions. Keep this file under 2,000 tokens so lightweight retrieval agents can consume it in a single pass.
Layer 2: Markdown Clean Endpoints
Each core HTML page should have an equivalent clean markdown endpoint or a direct export link listed in the manifest. For instance, linking to clean markdown versions of your service overviews allows scrapers to bypass navigation wrappers and extract facts with high fidelity.
Layer 3: Comprehensive Context (/llms-full.txt)
For detailed API references, product specifications, or comprehensive business FAQs, compile a unified llms-full.txt. This document concatenates your key documentation into a logical sequence with explicit H2 and H3 markdown delimiters.
| Component | Target File | Ideal Token Size | Primary Audience |
|---|---|---|---|
| Root Manifest | /llms.txt |
500 to 2,000 tokens | Fast conversational triage agents |
| Full Context | /llms-full.txt |
10,000 to 50,000 tokens | Deep research and synthesis models |
| Page Markdown | /blog/{slug}.md |
1,000 to 3,000 tokens | Specific query answer extraction |
Common mistakes when deploying an llms.txt setup guide
Many early adopters make the mistake of dumping their entire raw HTML database or marketing fluff into llms.txt. Unsubstantiated promotional language confuses generative models searching for factual attributes.
Another frequent failure is neglecting file maintenance. If you update your service offerings or pricing structure on your main site but leave outdated values in your text files, AI assistants will quote contradictory figures. Treat your markdown documentation with the same version-control rigor as your core code.
For teams tracking how AI assistants cite these assets over time, see my guide to measure AI search visibility. If you want hands-on assistance configuring your brand graph and machine-readable endpoints, explore our Generative Engine Optimization (GEO) services.
How I approach it
In the agent builds and GEO audits I run at METU Teknokent, I start by reviewing server logs to observe how bots like OAI-SearchBot and PerplexityBot traverse client URLs. Most websites waste over 70% of an AI agent's token budget on repetitive headers, sidebar links, and cookie banners.
I implement a build-step hook in Next.js or Astro that automatically regenerates /llms.txt whenever new cornerstone content or case studies are published. This guarantees that AI engines always encounter synchronized, high-density facts whenever they hit the server.
You can also read my books on AI systems and search strategy for deeper workflows on structured data architecture and conversational retrieval.
Key takeaways
- Place your primary
llms.txtfile directly in the public root directory. - Apply the 3-Layer llms.txt Hierarchy Framework to separate brief manifests from deep documentation.
- Strip marketing slogans and retain concise, verifiable facts with clear markdown headings.
- Synchronize updates so your markdown files mirror changes made to your primary HTML pages.
- Review bot crawl logs regularly to verify that AI search agents successfully fetch the file.
Frequently asked questions
Where should the llms.txt file be hosted?
Place the llms.txt file at the root of your domain, accessible at https://yourdomain.com/llms.txt. If you provide extended documentation, host llms-full.txt at the root as well.
Does having an llms.txt file guarantee AI citations?
No. The file functions like a sitemap for markdown-reading agents. It provides clean context and direct links, but models still decide what to retrieve based on prompt relevance and factual density.
What is the difference between llms.txt and llms-full.txt?
llms.txt acts as a curated index containing your core summary and links to markdown pages. llms-full.txt concatenates your primary knowledge base into a single comprehensive file for deeper context ingestion.
What to do next
- Audit your top 10 commercial and informational pages to extract their core factual takeaways.
- Draft a root
llms.txtfile matching the official specification with accurate entity names. - Deploy the file to your root web directory and verify HTTP 200 access using curl.
If you want to ensure AI search engines cite your brand accurately, book an SEO and GEO discussion with Bilal Dalgun.
Sources
- The llms.txt Standard Specification, https://llmstxt.org, published 2024-09-03.
- Google Search Central, Optimizing your website for generative AI features on Google Search, https://developers.google.com/search/docs/fundamentals/ai-optimization-guide, updated 2026-07-10.
- OpenAI, OAI-SearchBot Overview and Documentation, https://platform.openai.com/docs/bots, updated 2025-11-15.
Related posts
- 01
How to Measure AI Search Visibility: A Practical Framework
Measure AI search visibility with an evidence-to-action worksheet. Separate brand mentions, website citations and outcomes to decide what to fix next.
Read article - 02
The $50 Robot Hand That’s Embarrassing $50,000 Industrial Arms
OpenClaw and generative AI are doing to robotic grippers what Linux did to enterprise software. And the industry hasn't fully caught up yet.
Read article - 03
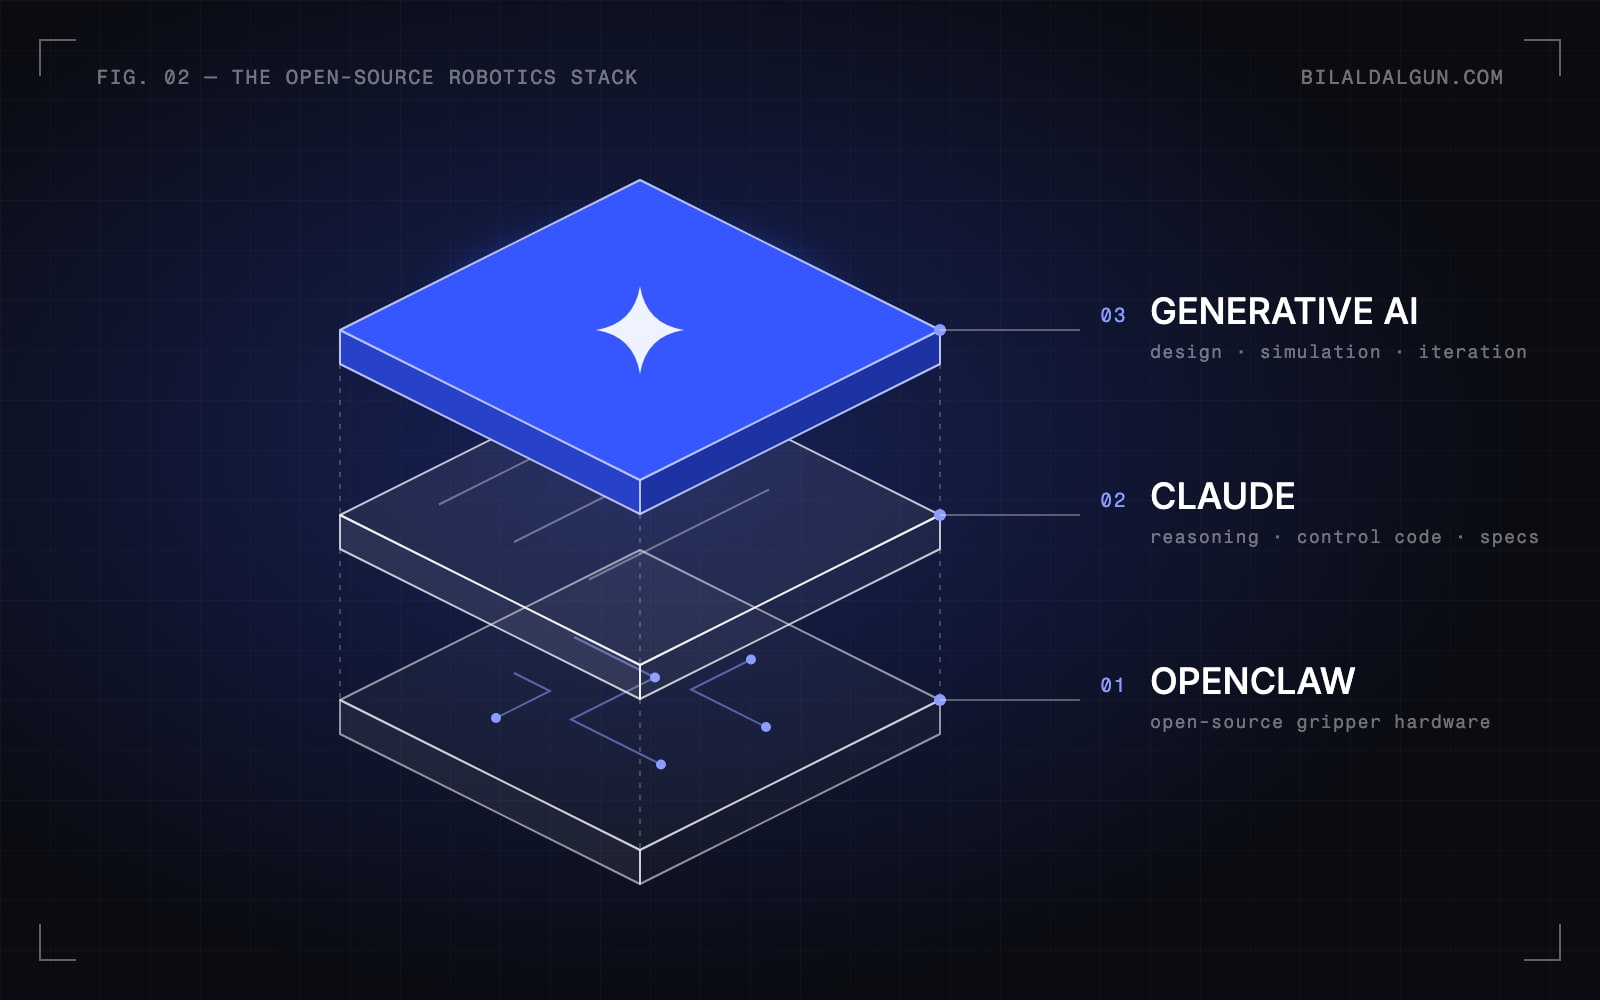
OpenClaw + Claude + Generative AI: The Open-Source Stack Quietly Building Tomorrow’s Robots
The open-source stack quietly building tomorrow's robots isn't quiet because it's small. It's quiet because the people building with it are too busy building.
Read article